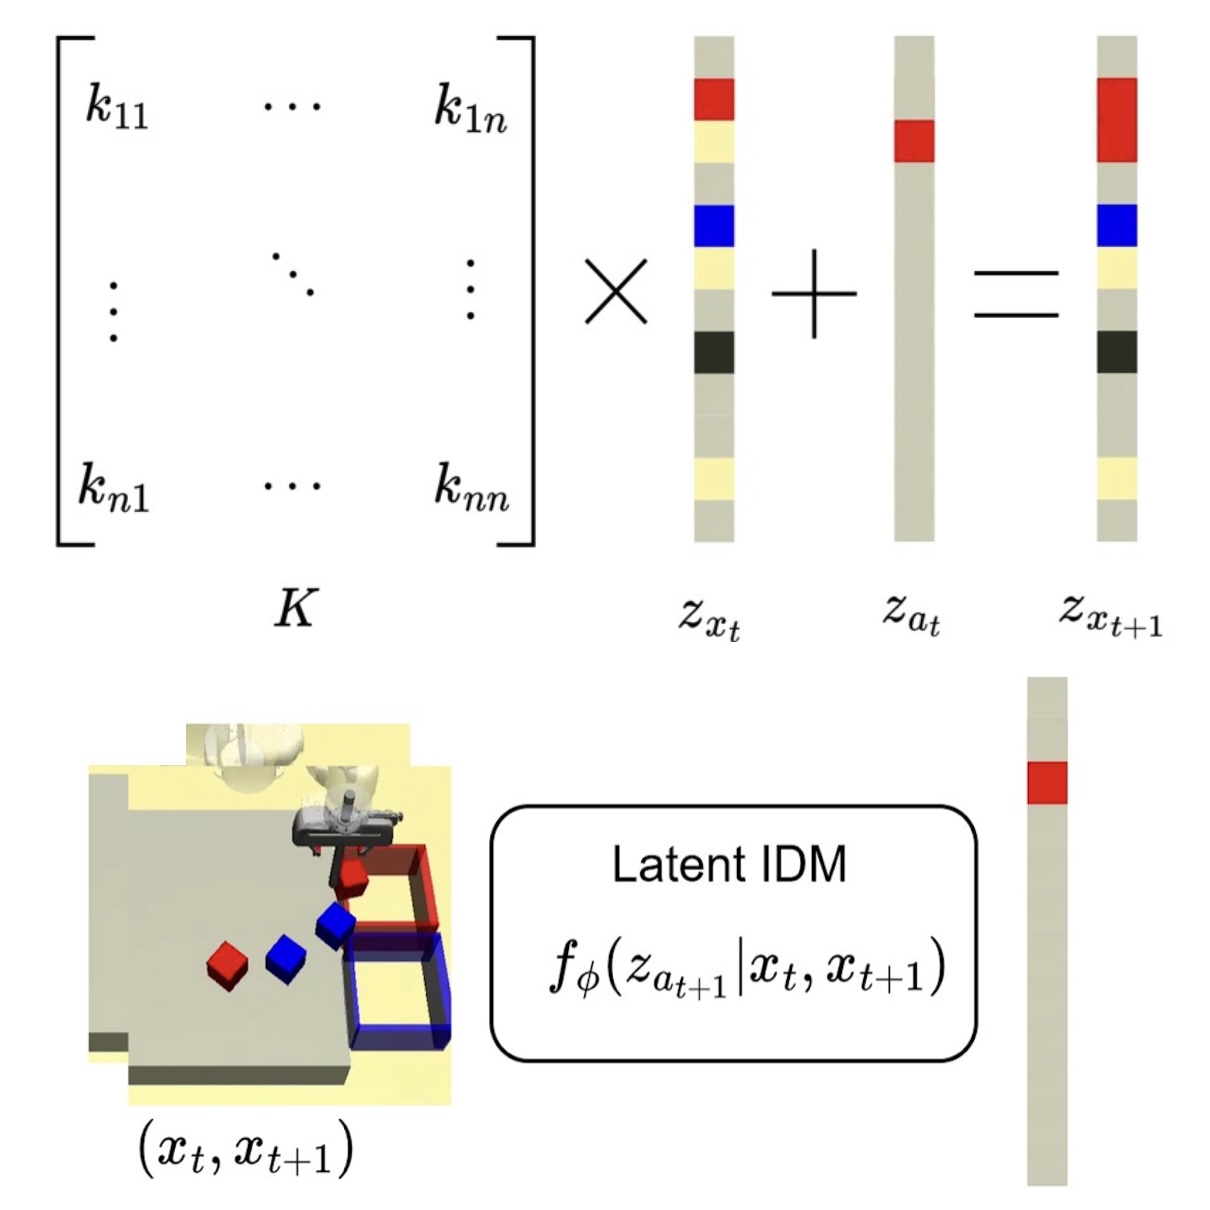
KOAP: Imitation Learning with Limited Actions via Diffusion Planners and Deep Koopman Controllers
We introduce KOAP for imitation learning with limited actions.

Laruso blog features productivity, tips, inspiration and strategies for massive profits. Find out how to set up a successful blog or how to make yours even better!
We introduce KOAP for imitation learning with limited actions.
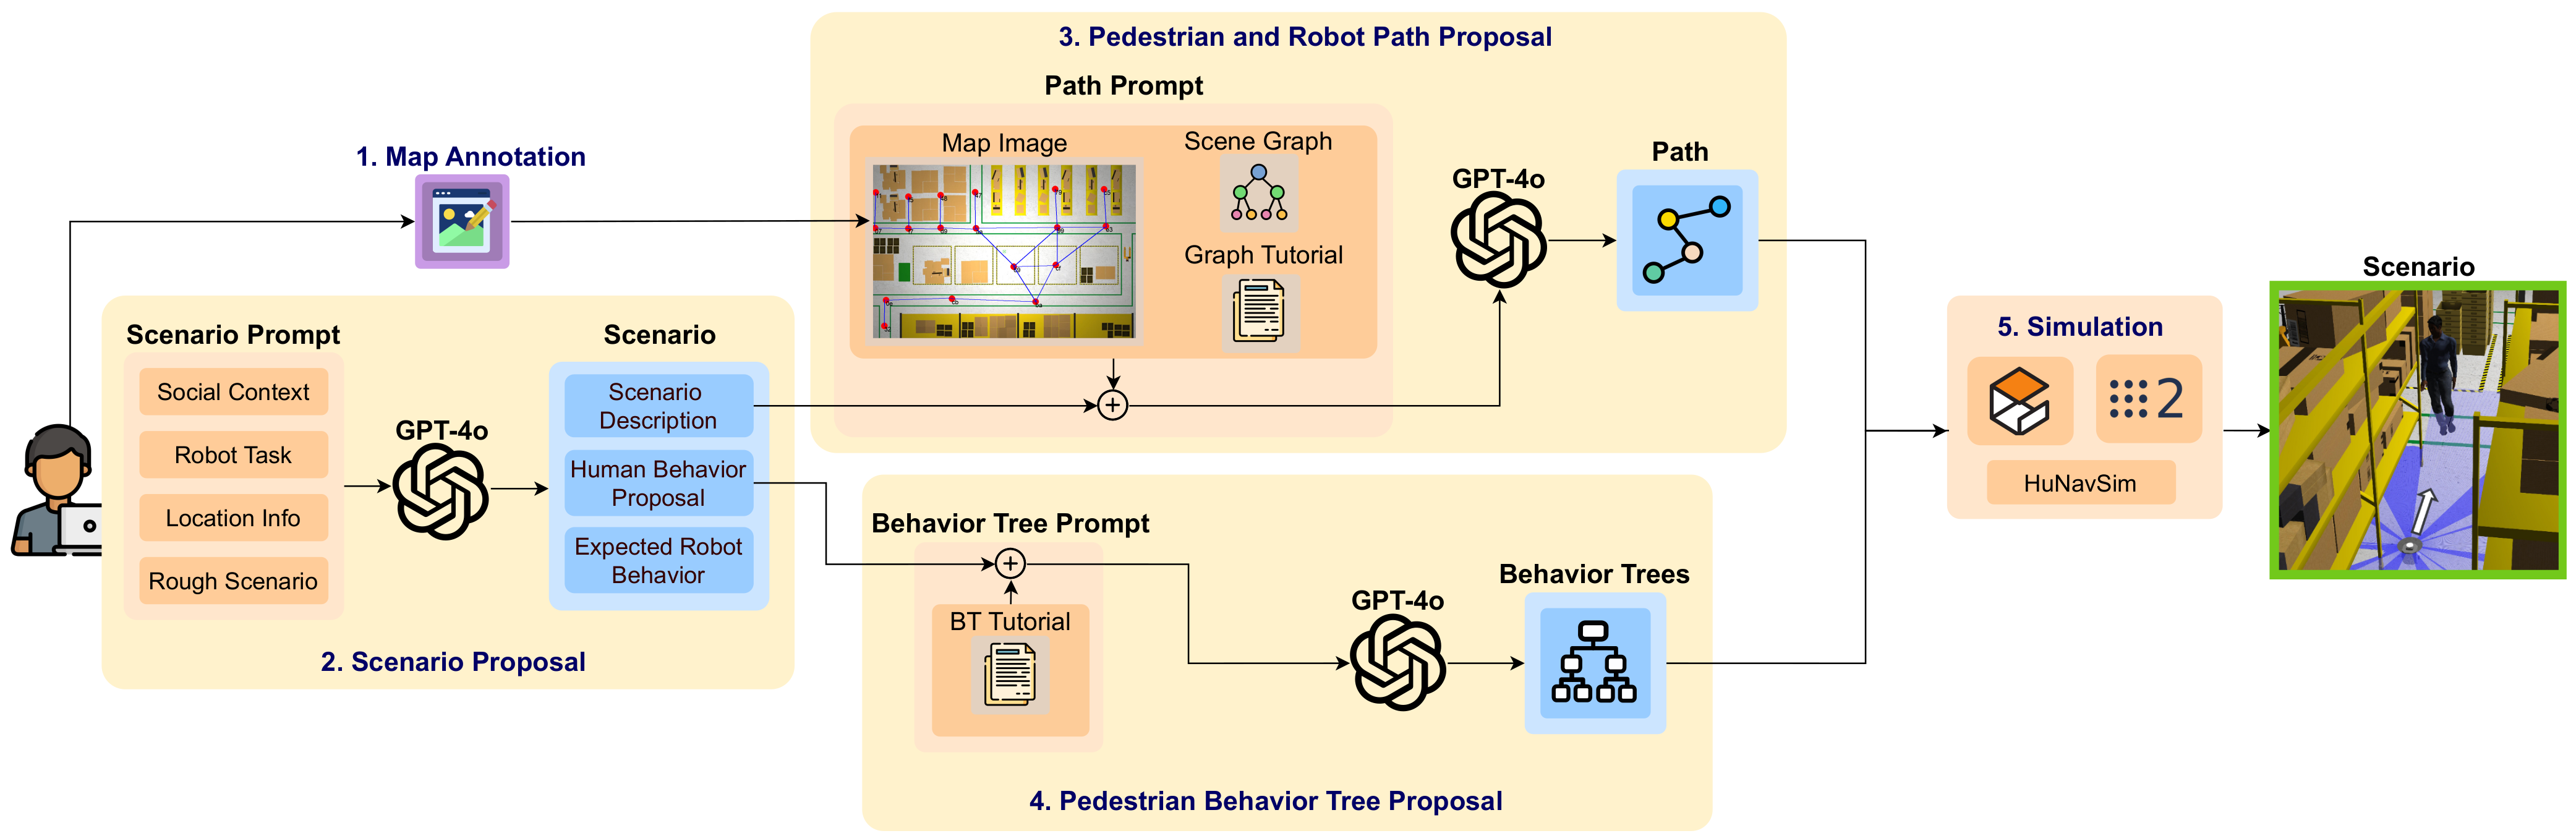
We design an LLM-driven social-scenario simulation pipeline (SocRATES) to enable more holistic evaluation of social navigation algorithms. SocRATES generates context- and location-appropriate scenarios from simple text and image-based inputs, thus reducing the labor-intensive task of scenario proposal and synthesis that is typically required for scenario-based testing.
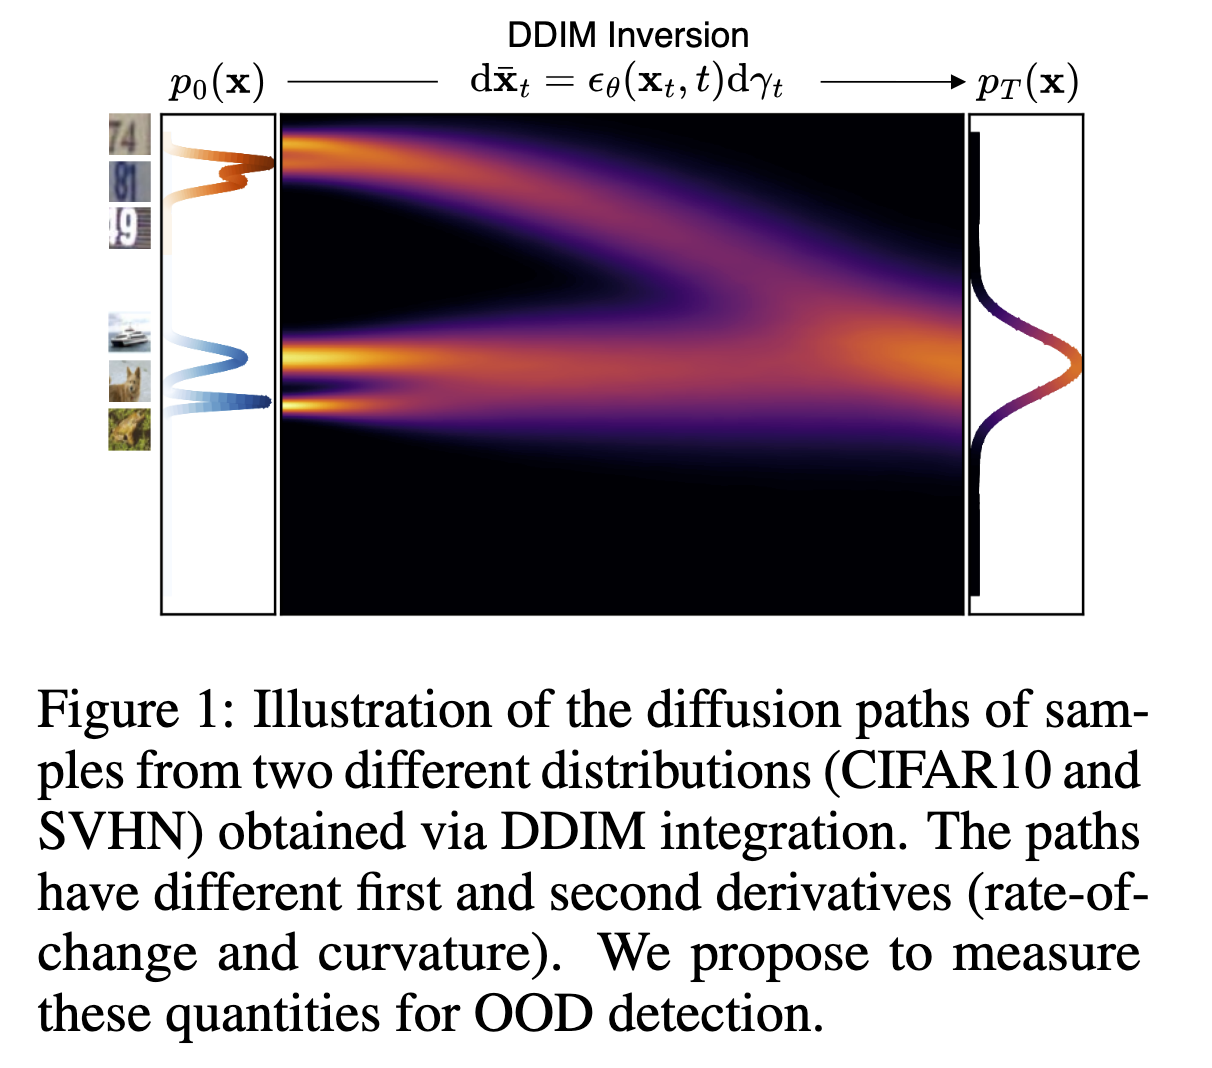
We show that a single unconditional diffusion model performs competitively in out-of-distribution detection tasks by measuring the rate-of-change and curvature of diffusion paths connecting data samples to the standard normal distribution.
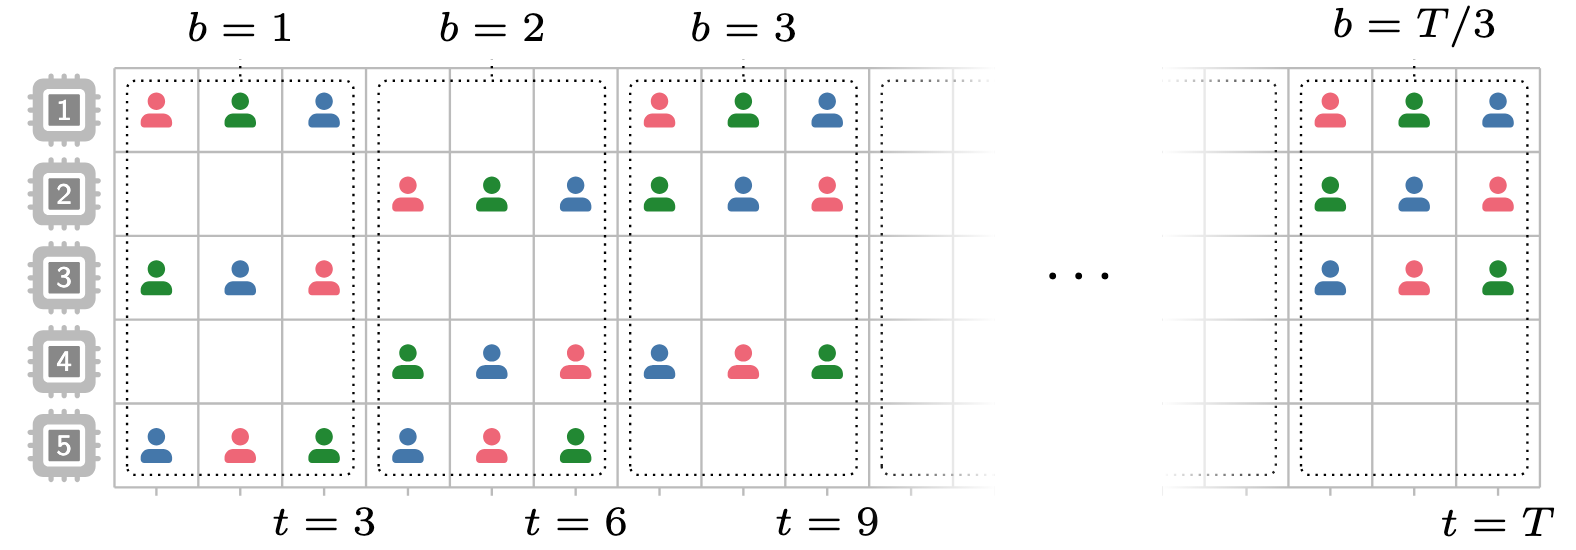
We address a problem where an agent assigns users to arms in a stochastic multi-armed bandit setting to maximize the minimum expected cumulative reward for all users. It presents a UCB-based policy with upper bounds on cumulative regret and an impossibility result for policy-independent approaches.
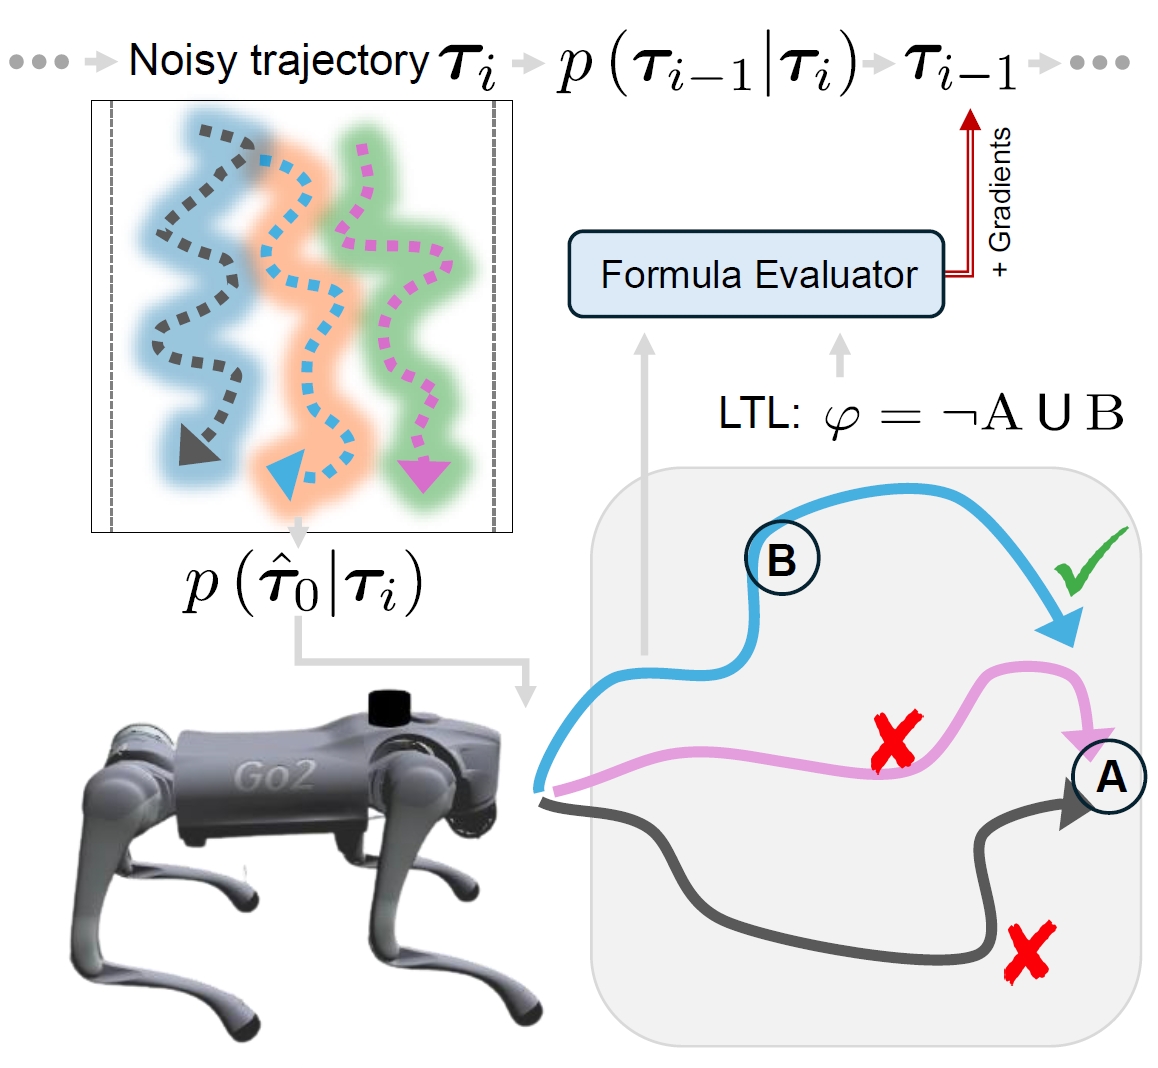
We develop a safe planning method for trajectory generation by sampling from diffusion model under different LTLf constraints.
We extend gradient flow methods to a variety of high-quality image synthesis tasks using a novel density ratio learning method.
Harold gave a well-received Keynote at ICRA’24 on our group’s work on generative modeling and robotics! He spoke about two of our recent works on new kinds o...