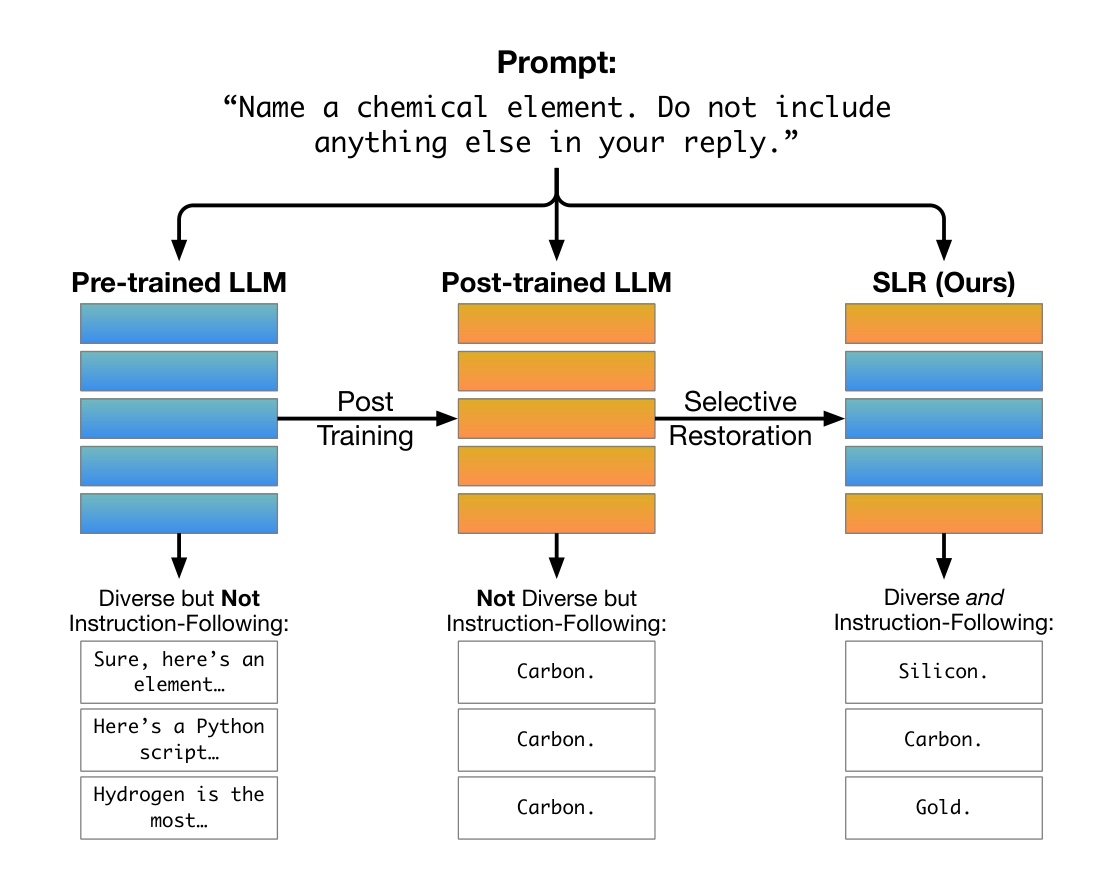
Not All Layers Need Tuning: Selective Layer Restoration Recovers Diversity
A training-free method that restores selected layers of a post-trained LLM to their pre-trained weights, recovering output diversity while preserving output quality.

Laruso blog features productivity, tips, inspiration and strategies for massive profits. Find out how to set up a successful blog or how to make yours even better!
A training-free method that restores selected layers of a post-trained LLM to their pre-trained weights, recovering output diversity while preserving output quality.
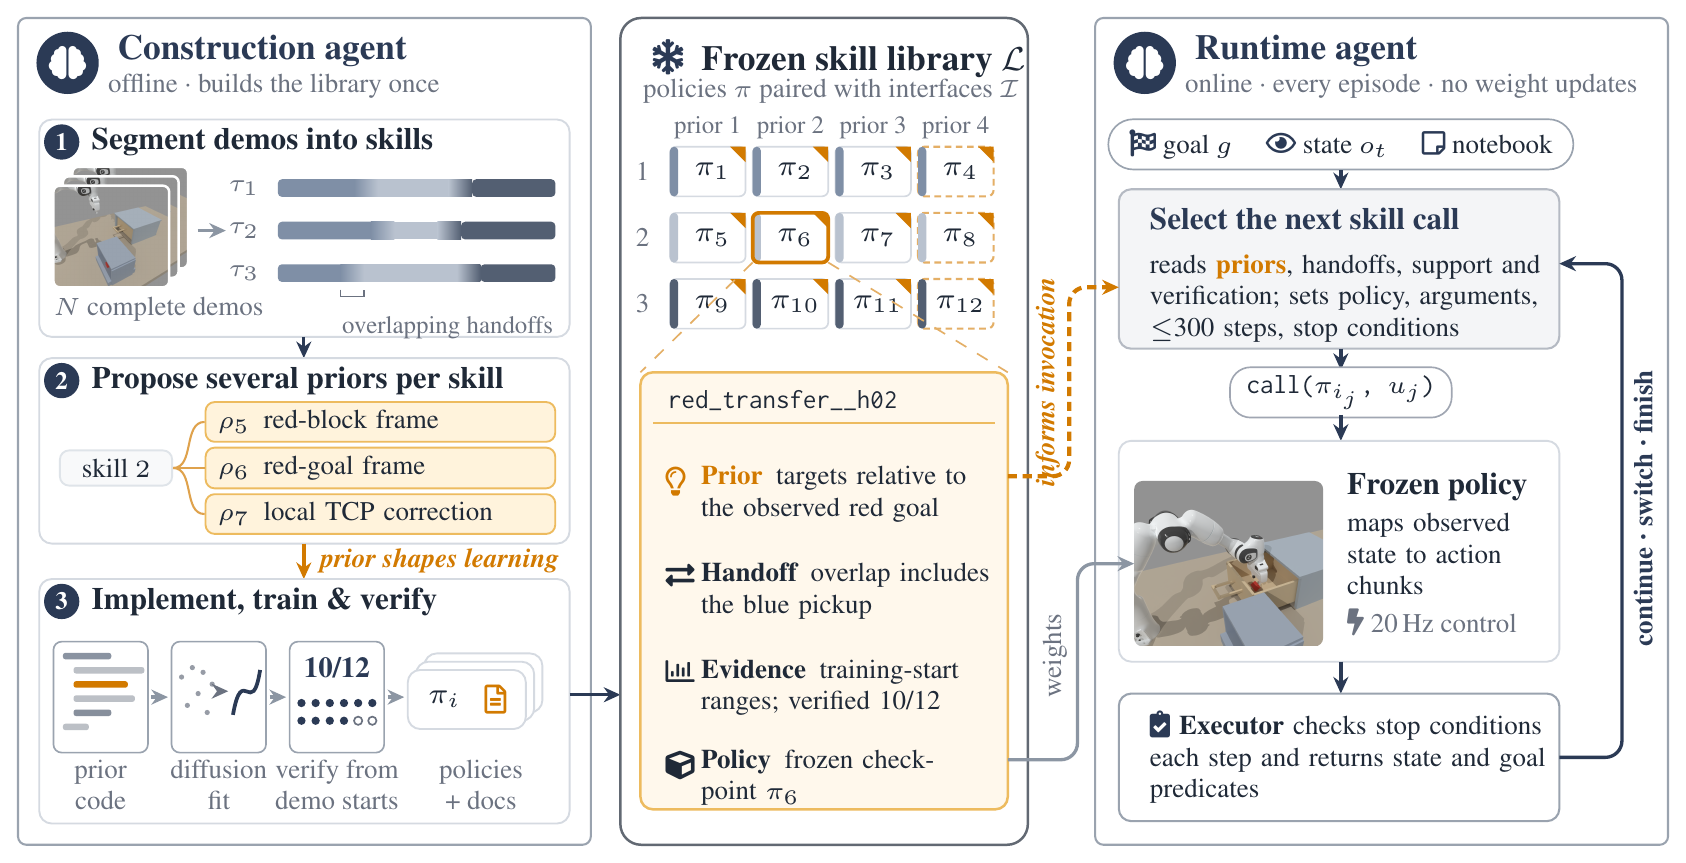
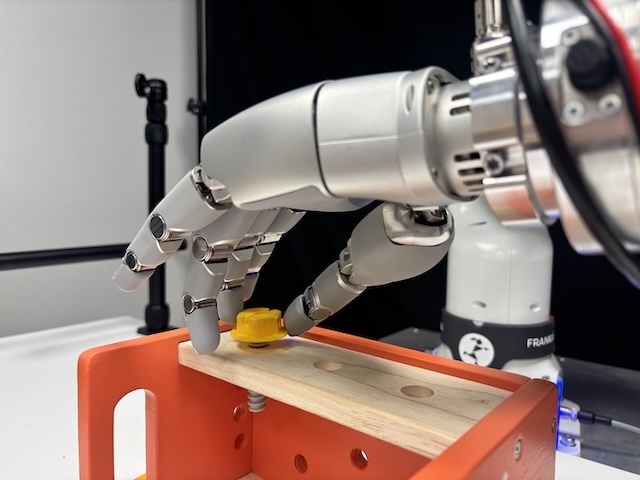
An agentic robot learning framework connecting policy learning with agent-based skill selection and composition through structural priors.
Eugene Lim has graduated and is now Dr. Lim. Congratulations Eugene! He will be joining Mathrix as a Quant Analyst.
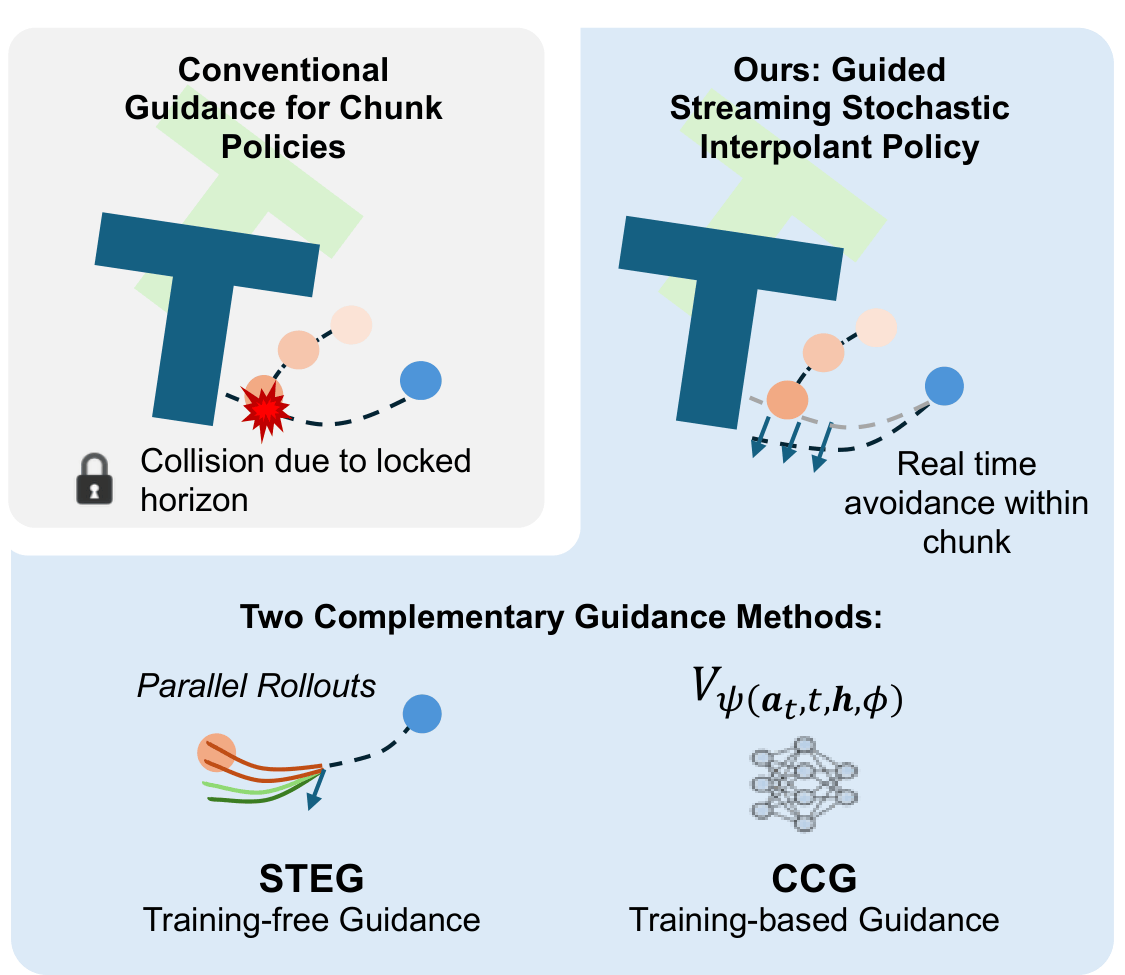
A principled inference-time guidance framework for streaming generative robot policies, enabling fast, reactive obstacle avoidance within the action chunk.
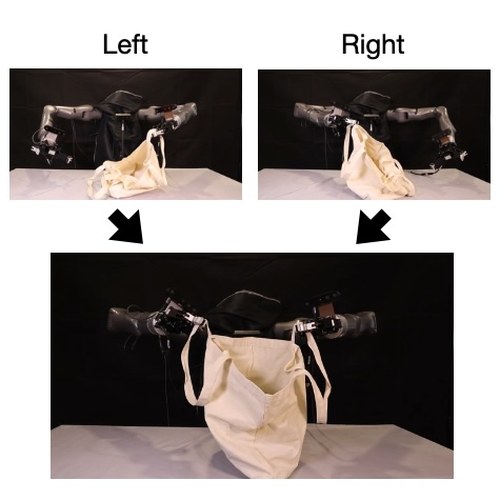
A dual-arm manipulation framework that enables skill reuse—recomposing learned single-arm skills into novel left–right pairings to tackle combinatorial diversity.
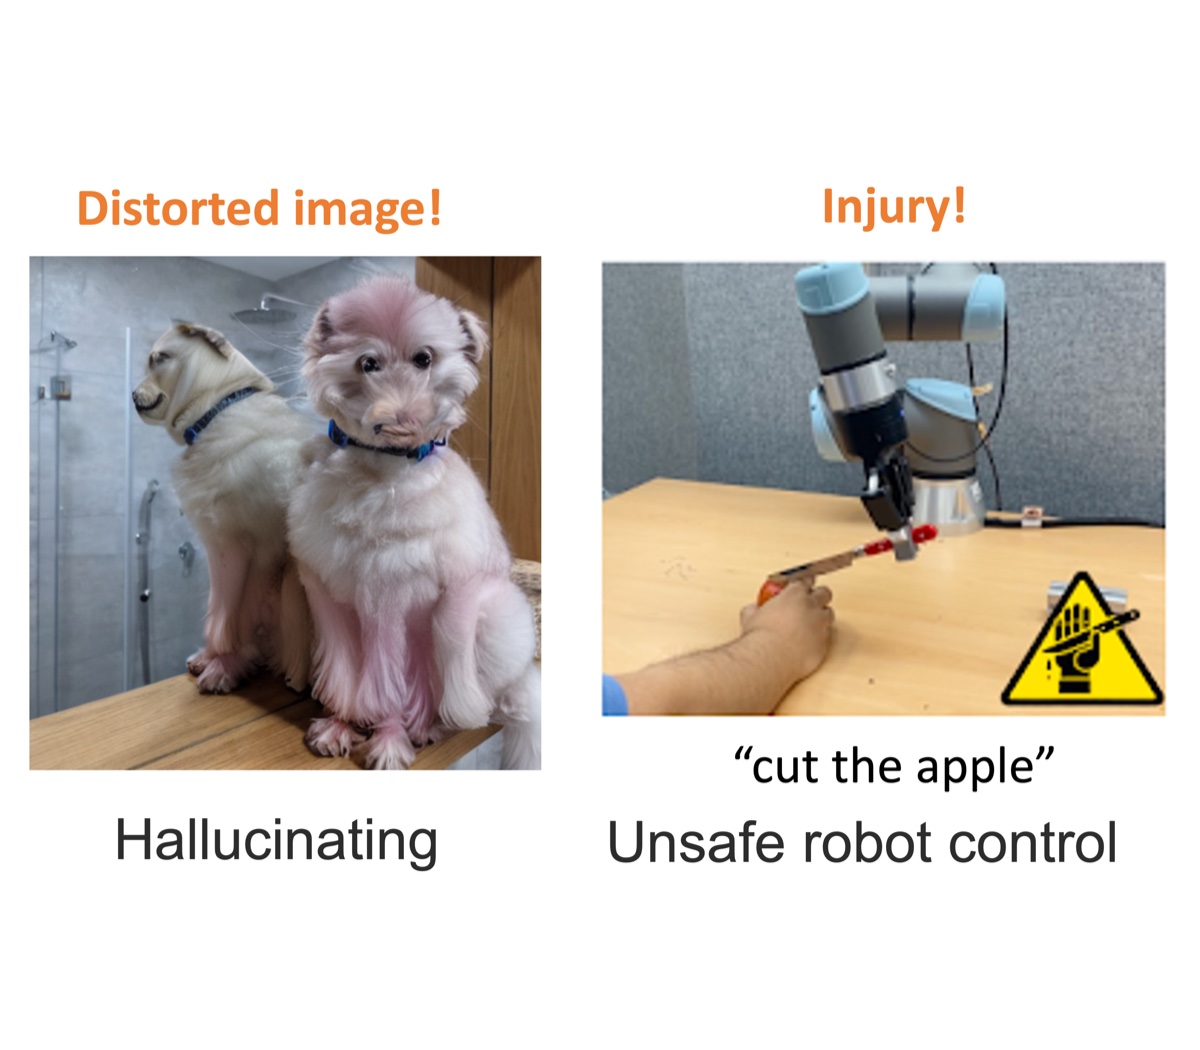
We introduce a plug-and-play module that corrects off-manifold drift when guiding flow models with multiple rewards at inference time.
A self-supervised tactile backbone that learns shared representations across heterogeneous tactile sensors, boosting perception and contact-rich manipulation—even with sensors unseen during pretraining.